What work is authorized now, under what limits, on what evidence, and what finding would require the organization to restrict or stop it?
A defensible authorization decision applies to a defined workflow, not AI in the abstract. The AI-Supported Work Authorization Cycle begins by inventorying the use and assigning ownership. It then defines the work and risk, sets an authority envelope, tests the complete human-AI workflow on representative cases, authorizes only the scope supported by evidence, and reconsiders the decision when the workflow changes or fails.
The method is designed for pharmaceutical manufacturing and quality operations. It works alongside the lifecycle-oriented, risk-based practitioner guidance in GAMP Guide: Artificial Intelligence and GAMP 5, while adding a local authorization decision for each configured human-AI workflow. It does not replace existing GMP responsibilities, validation, data-integrity controls, Part 11 analysis, or quality-unit accountability.
Public examples support the need to manage evidence access, human judgment, and change, but each organization must establish the evidence and controls appropriate to its own work. GxP Frame’s reference toolkit provides a use inventory, Gate Decision Record, workflow scoring sheet, AI Authorization Register, Independent Effectiveness Review Record, User Guide, Role Quick-Start Cards, and Adjudication Protocol that turn the cycle into a practical starting point.
The method states acceptance criteria in terms an auditor can check. For the deviation-chronology pilot below, authorization requires zero critical omissions across at least 59 independent, representative holdout cases, supporting a true critical-omission rate no higher than about 4.95% at 95% one-sided confidence. For the same 5% claim, one critical omission requires at least 93 total cases with no further failures; demonstrating a rate below 1% requires 299 zero-failure cases.
Those figures apply to the deviation-chronology worked example and the consequence it carries. They are not universal thresholds. Evidence should be scaled to the workflow's authority, downstream consequence, and ability to affect a regulated conclusion. Lower consequence warrants less evidence, not none. A bounded transformation that cannot create, change, approve, or determine a regulated conclusion requires evidence appropriate to that limited role; a workflow that can influence or execute a regulated action warrants stronger evidence.
About the examples in this paper. The Gate Decision Record, acceptance criterion, and site scenario are worked examples built to demonstrate the method. They are not drawn from any organization's internal implementation, results, or reported incidents. Figures are constructed to be arithmetically correct, not to represent observed performance.
What this paper does not establish. This paper does not establish that every AI-supported workflow is acceptable, demonstrate real-world performance of the Cycle or its worked examples, replace validation or applicable GMP responsibilities, or authorize a workflow without locally approved evidence and accountable quality decisions.
Start Monday with Stage 0: inventory actual AI use, including unapproved use; identify the systems and records involved; and assign a process owner, system owner, data owner, and quality owner before deciding what may proceed.
Readers who want the method in one record can start with the worked Gate Decision Record after Figure 1, then continue to the full site walkthrough.
What must be true before the work proceeds
Consider a deviation summary prepared by AI. The chronology looks sound, the documents are linked, and a reviewer approves it. Months later, someone finds an equipment record that contradicts the conclusion. The summary left it out. To understand this failure, we need to know which records the system could access, how it selected them, what the reviewer could see, and why the summary was approved.
AI must not support pharmaceutical quality work until the organization has defined the task, established what the system may do, and tested whether the complete human and AI workflow can perform representative work reliably. The resulting evidence must determine whether the work may proceed, what limits apply, and what findings require correction, restriction, or withdrawal.
This approach connects four questions that organizations often address separately: whether the evidence is adequate, whether the system has appropriate authority, whether people can perform their assigned role, and whether the organization can find and correct failures. Passing a model test or completing a course does not establish that the combined workflow will produce acceptable work. A qualified person can still miss a record that changes the conclusion, especially when the system controls which evidence reaches the reviewer.
I developed this operating method through earlier work on manufacturing readiness, governance by design, AI qualification, and agent authority. The method treats the relationship among the person, system, version, use case, source environment, and granted authority as the operating unit.
The focus here is pharmaceutical manufacturing and quality operations. Other GxP settings require controls suited to their records, decisions, and governing requirements.
What industry experience tells us
Industry experience supports the need to evaluate the work around the technology. Roche describes trusted data, employee development, process redesign, and governance as connected conditions for useful AI outcomes. McKinsey's pharmaceutical analyses similarly place talent and change management alongside strategy, technology, analytics, and data, and call for operators and technical staff who can recognize errors and make informed decisions. [1–2]
Lilly's responsible-use disclosure assigns employees accountability for AI outputs and describes evaluation for specific uses. GSK reports generative AI across manufacturing sites for examining historical investigations, alongside further inspection-readiness work. These accounts show organizations confronting evidence access, human judgment, and workflow design together. [3–4]
The useful question is whether an organization can use available evidence to make a defensible decision about a particular AI-supported job.
The control basis the cycle sits on
The cycle sits inside existing quality responsibilities, record requirements, and lifecycle controls. It does not replace them, and no source below establishes that completing these six stages is sufficient authorization.
| Requirement or framework | What it requires or supports here | What it does not establish |
|---|---|---|
| Quality-unit responsibility | 21 CFR 211.22(c) requires the quality control unit to approve or reject all procedures and specifications impacting drug-product identity, strength, quality, and purity. In Warning Letter 320-26-58 (April 2, 2026), FDA found that a homeopathic drug manufacturer “used AI to create drug product specifications, procedures, and master production or control records” and stated that the failure to review those documents for accuracy and CGMP compliance violated 21 CFR 211.22(c). [5] | A universal AI certification, permission to outsource the regulated decision, or any conclusion about the adequacy of a mature governance program. The cited firm had broad baseline CGMP failures, including violations of 21 CFR 211.165(b) and 211.84(d). |
| Qualified personnel | 21 CFR 211.25 requires education, training, experience, or their combination to enable assigned functions, with continuing training as needed. [6] | That course completion or awareness training demonstrates performance in a configured human-AI workflow. |
| Quality risk management | ICH Q9(R1) supports effort, formality, and documentation proportionate to risk, uncertainty, importance, and complexity across a lifecycle. [7] | That risk language can excuse an unacceptable practice or unsupported conclusion. |
| FDA AI credibility framework Status as of September 21, 2026: January 2025 draft guidance; nonbinding and not for implementation. | FDA's January 2025 draft guidance proposes a seven-step, risk-based framework for establishing the credibility of AI model outputs within a defined context of use. It applies where AI produces information or data supporting regulatory decision-making about drug safety, effectiveness, or quality. FDA defines that term to include actions by manufacturers and other parties in conformance with CGMP, not only FDA's own determinations. The proposed level of oversight, stringency of credibility assessment, acceptance criteria, risk mitigation, and documentation should be commensurate with model risk and tailored to the context of use. [39] | A binding FDA requirement, approval of a particular AI technique, or a complete governance method for every internal workflow. The draft does not address AI used in drug discovery or operational-efficiency uses that do not affect patient safety, drug quality, or the reliability of nonclinical or clinical-study results. An internal workflow that affects drug quality is not excluded merely because it is internal. |
| Pharmaceutical quality system | ICH Q10 connects management responsibility, knowledge management, monitoring, CAPA, change management, and management review. [8] | That this particular six-stage cycle is a regulatory requirement. |
| Electronic equipment and records | Where applicable, 21 CFR 211.68 supports authorized changes, checks proportionate to system complexity and reliability, and backup safeguards. [9] | That every prompt or output is a regulated record or that an AI use is acceptable. |
| Data integrity and provenance | FDA data-integrity guidance and PIC/S PI 041-1 support reliable, accurate, complete, consistent, enduring, and available records, with data governance based on process and technology risk. [10–11] | That a fluent answer or a citation list proves that the evidence set was complete. |
| Human-AI interaction | Joint FDA and EMA good-AI-practice principles support examining the complete system, including human interaction, provenance, multidisciplinary expertise, and continuing performance. [12] | A statutory qualification scheme or endorsement of this method. |
| European AI proposals Status as of September 21, 2026: draft. Consultation ran July 7 to October 7, 2025, and is closed. EMA held a multistakeholder workshop on June 30 and July 1, 2026, to gather expert input and stated that it was still considering the consultation results. No publication or application date has been announced. | The effective EudraLex listing must be distinguished from the consultation draft for Annex 22. [13–14] | That draft Annex 22 is effective law or that adding a reviewer makes a critical function non-critical. |
| GAMP lifecycle guidance | GAMP Guide: Artificial Intelligence and GAMP 5 provide lifecycle-oriented, risk-based practitioner guidance for GxP systems. [15–16] | That GAMP requires these six stages or these specific records. |
| AI governance systems | NIST AI RMF 1.0 calls for AI inventories, defined roles, accountability, monitoring, and documented risk decisions. ISO/IEC 42001:2023 provides a management-system structure for responsible AI risk and opportunity management. [17–18] | A pharmaceutical authorization decision, GMP compliance, or acceptable performance for a specific use. |
How the authorization cycle relates to GAMP
This is a conceptual crosswalk. GAMP supplies lifecycle-oriented, risk-based practitioner guidance; the cycle adds a local gate decision for a configured human-AI workflow. [15–16]
| Authorization stage | Related lifecycle concern | Added local decision |
|---|---|---|
| 0. Inventory and ownership | Governance, system inventory, intended use, supplier and organizational responsibilities | Register, contain, prohibit, or assign named ownership for each actual use |
| 1. Define work and risk | Requirements, intended use, process understanding, risk assessment, and lifecycle planning | Approve, narrow, or reject the specific human-AI workflow scope |
| 2. Set authority and records | Security, access, data integrity, electronic records, interfaces, and control design | Authorize bounded read, recommend, change, or approval functions, or prohibit them |
| 3. Test the workflow | Risk-based verification, test evidence, acceptance criteria, traceability, and supplier evidence | Authorize a bounded pilot, correct, narrow, or stop based on representative work |
| 4. Authorize and monitor | Release, operation, performance monitoring, incident signals, and periodic review | Authorize routine use, continue, restrict, investigate, suspend, or expand |
| 5. Change, correct, retire | Change control, problem management, corrective action, re-verification, continuity, and retirement | Reinstate, narrow, requalify, stop, or retire the workflow |
The AI-Supported Work Authorization Cycle
The following cycle turns the argument into a set of gate decisions. Each stage produces evidence for proceeding, narrowing the use, correcting it, or stopping it.
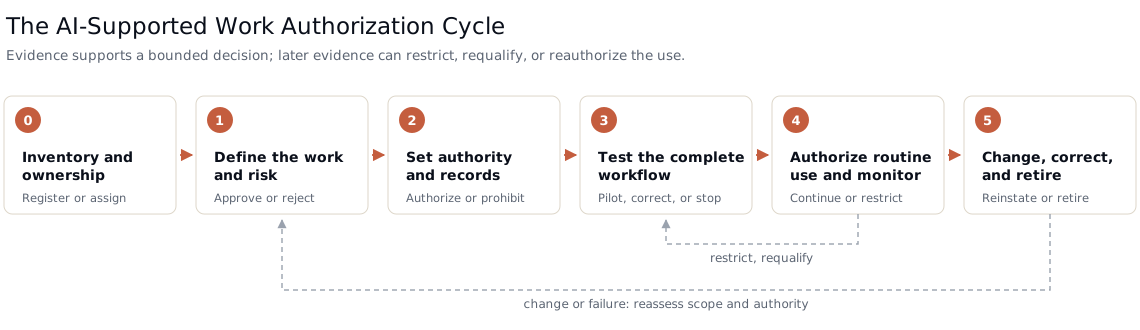
Explore the cycle as a responsive visual guide, with the original three-page HTML available to view.
Each gate must have a named decision maker and a recorded outcome. Pilot authorization does not authorize routine use, and routine-use authorization does not authorize expansion to a new task, source, site, or authority level. The Gate Decision Record must identify the evidence reviewed, accepted conditions, unresolved risks, accountable decision maker, and trigger for reconsideration. Completed activities are not authorization.
This record is one of eight artifacts in the AI Work Authorization Toolkit, alongside the use inventory, workflow scoring sheet, AI Authorization Register, Independent Effectiveness Review Record, User Guide, Role Quick-Start Cards, and Adjudication Protocol. See the toolkit.
| Stage | Question | Required evidence | Accountable owner | Gate decision |
|---|---|---|---|---|
| 0. Inventory and ownership | What AI is in use, including unapproved use, and who owns each use? | Use inventory, systems and data accessed, users, suppliers, named process, system, and quality owners | AI governance lead and quality unit | Register, contain, prohibit, or assign ownership |
| 1. Define the work and risk | What task and decision will AI support, and what could failure affect? | Intended use, source boundary, applicable requirements, baseline process and baseline measurement, risk assessment | Process owner and quality owner | Approve the scope, narrow it, or reject it |
| 2. Set authority and records | What may the system read, recommend, change, or approve, and which records must be retained? | Permissions, prohibited actions, approval design, record and signature requirements, retention plan | System owner, quality owner, IT, and data owner | Authorize bounded functions or prohibit them |
| 3. Test the complete workflow | Can the system and people perform representative work under realistic conditions? | Challenge cases, system results, reviewer performance, omissions, false alarms, time, and recovery tests | Evaluation owner and quality unit | Authorize a pilot, correct, narrow, or stop |
| 4. Authorize routine use and monitor | Does pilot evidence justify routine use, and does performance remain acceptable? | Pilot results, unresolved risks, incidents, near misses, overrides, workload, outcome measures, drift indicators, and user feedback | Process owner and quality unit | Authorize routine use or expansion, continue, restrict, investigate, or suspend |
| 5. Change, correct, and retire | What changed, what was affected, and did the response work? | Change impact, regression results, requalification, corrective-action evidence, records, dependencies, and continuity plan | Change owner, system owner, and quality unit | Reinstate, narrow, stop, or retire |
Stage 0: Inventory and ownership
Stage 0 matters because an organization cannot govern a use it has not identified. The inventory must describe actual work, not merely list vendors. "AI used in quality" is too broad. Each entry must identify the task, source systems, output, users, downstream decision, and whether the system can act. Unapproved consumer-tool use belongs in the same inventory process because it may expose regulated information or create outputs that enter the quality system without an accountable owner.
Ownership must be divided clearly. The process owner defines the work and acceptable outcome. The system owner maintains the configured service, integrations, access, and technical evidence. The data owner governs the sources and permitted uses of information. The quality unit determines whether the proposed controls and evidence support the regulated use and retains its existing approval responsibilities. An AI governance body can set common policy, coordinate expertise, and resolve cross-functional questions, but it must not become a substitute owner for every local process. Suppliers provide evidence and change information; they do not accept the manufacturer's regulated decision on its behalf.
The inventory must remain connected to procurement, access management, incident reporting, and retirement. Otherwise, it becomes a periodic spreadsheet that misses the work it was created to govern. New integrations, expanded permissions, unexpected outputs in controlled records, and reports of consumer-tool use must trigger inventory review rather than wait for an annual reconciliation.
The cycle does not require the same ceremony for every use. A bounded formatting tool and an agent that can alter a regulated record present different questions. Evidence, documentation, and review should follow the significance, uncertainty, and complexity of the work.
Stage 1: Define the work and risk
I use the shorthand person × system × version × use case. For an agent, add the source environment and authority envelope: the systems and records it may access, the actions it may take, the approvals it needs, and the conditions that stop it. Readiness depends on this complete relationship and can change when any part changes. [19]
"Prepare a draft chronology from a defined set of approved deviation records for an investigator who verifies each consequential statement" can be evaluated. "AI for Quality" cannot. A useful intended use identifies:
- Task. The bounded work the system supports.
- Source boundary. The systems, records, and data it may use.
- Expected output. The artifact or recommendation it may produce.
- User. The role responsible for operating or reviewing it.
- Downstream decision. The decision the output may inform.
- Prohibited actions. What the system may not do.
The intended use must also identify how failure could affect product quality, patient safety, data integrity, compliance, or availability.
FDA's proposed credibility framework begins with a specific question of interest, a defined context of use, and an assessment of model risk. The Authorization Cycle applies the same discipline to the complete operational workflow: not only whether a model can produce a credible output, but whether people, systems, evidence sources, permissions, and controls together support allowing that output to inform or perform defined GxP work. FDA's own manufacturing example applies this question-of-interest logic to AI-supported fill-volume assessment. This is an operating-method extension, not a claim that FDA has prescribed this cycle. [39]
The system description must include the interface, connected tools, retrieval sources, configurations, permissions, and points where a person must intervene. A capable reviewer may face a materially different job after a retrieval change, model update, new product, altered interface, or grant of write access. The name of the product may remain unchanged while the qualified state has changed.
Define the baseline process at the same time. If the current human process already misses records, produces inconsistent classifications, or takes an unacceptable amount of time, the comparison should expose that weakness. The objective is not to preserve a flawed baseline. It is to determine whether the proposed workflow produces acceptable work and whether its benefit justifies the new risks and controls. A comparison that measures only the AI condition can misattribute pre-existing failures to the tool or conceal failures that both methods share.
The baseline must be measured, not only described. Record the time required to reach an acceptable result today, the review effort that result already consumes, and the rate of consequential error where that error is defined and can be measured. A described baseline supports a comparison of steps. A measured baseline supports a comparison of outcomes. Without one, the organization cannot later determine whether the new workflow improved the work or only relocated the effort. The measurement does not need to be elaborate. It needs to exist before the workflow changes because it cannot be reconstructed afterward.
Different technologies require different evidence. A classifier used in visual inspection, a predictive model used in process analysis, and a language model drafting an investigation create different failure modes. For a classifier, evaluation should address independent test data, important defect classes, subgroup performance, calibration, and the consequences of false positives and false negatives. A strong average can conceal poor performance on a rare but consequential defect.
For generative systems, verification must address meaning. A fluent sentence can reverse a negation, remove a qualification, or imply causation where the source shows only sequence. Agreement between repeated answers gives limited reassurance when the same missing source or unsupported inference drives each answer. Tested calculation tools must perform controlled calculations, deterministic rules must enforce permissions, retrieval must identify candidate evidence, and generative AI may organize or draft material within those boundaries. Test each component for its assigned job and then test the complete workflow.
The product and task also shape the challenge cases. In QC, a reviewer may need to find omitted raw data, a dilution error, a method-version mismatch, or an unsupported explanation for an out-of-specification result. In technology transfer, the risk may be extrapolation beyond studied conditions. In patient-specific manufacturing, identity and custody require explicit testing because a plausible summary attached to the wrong patient or material is a serious failure. For external partners, the system must preserve site identity, supplier status, quality-agreement responsibility, and provenance across organizational boundaries.
Stage 2: Set authority and preserve decision evidence
As AI moves from producing content to taking action, the organization needs a precise account of what each system may observe, interpret, recommend, decide, execute, and approve. Capability describes what the technology can do. Permission describes what the organization has authorized it to do. The Authority Envelope must contain the following elements. [20]
| Element | Recorded where |
|---|---|
| Accessible systems and records | Gate Decision Record Authority Envelope |
| Allowed operations | Gate Decision Record Authority Envelope |
| Prohibited actions | Gate Decision Record Authority Envelope |
| Approval points | Gate Decision Record Authority Envelope |
| Stop conditions | Gate Decision Record Authority Envelope and monitoring plan |
| Accountable person | Gate Decision Record decision and approval fields |
Part 11 must be applied with equal precision. It does not make every AI prompt or output a Part 11 record. Under FDA's scope guidance, Part 11 applies when records required by predicate rules are maintained electronically in place of paper or relied upon for regulated activities, when designated records are submitted electronically to FDA, and when electronic signatures are intended to serve as required signatures. The organization should determine which records and signatures fall within that scope. For applicable systems, authority checks, operational checks, access controls, accountability for electronic signatures, and reliable records are directly relevant to AI-supported approvals and actions. [21]
Where 21 CFR 211.68 applies to automatic, mechanical, or electronic equipment used in drug manufacturing, subsection (b) requires appropriate controls so that changes to master production and control records or other records are instituted only by authorized personnel. It also addresses checks on computer input and output according to system complexity and reliability, together with backup safeguards. These requirements support the authority envelope and record design, but they do not prescribe this paper's workflow or establish that an AI use is acceptable. [9]
Make that determination here, before a system has generated months of records. The team must identify which artifact is the regulated record, which supporting evidence must remain linked to it, whether an electronic approval is intended to have the force of a required signature, and what information must be available during an investigation or inspection. An AI interaction may be transient in one workflow and consequential evidence in another. The applicable predicate rule and actual business reliance determine the treatment.
These limits require technical enforcement. An instruction telling an agent not to approve a record provides weak protection if its credentials permit approval. The agent must have its own attributable identity and only the access required for its assigned function. It must not inherit all the privileges of the employee who launches it.
Approval must remain tied to the state reviewed. If someone approves an update and the underlying record changes before the agent acts, the system must determine whether the approval still applies. Where the change undermines the original basis, the action requires another review. Permission to retrieve records does not confer permission to determine root cause, open a corrective action, or approve closure.
The record must let another person reconstruct what happened:
- The task.
- Relevant inputs.
- Source versions.
- Retrieval results.
- Configuration.
- Tool actions.
- Output.
- Changes.
- Reviewer response.
- Approval.
- Resulting system state.
A model's narrative explanation of its answer is not proof of its internal path. Keep that narrative distinct from verifiable inputs, outputs, actions, and human reasons.
This is decision provenance rather than logging alone. The audit trail may show that a field changed at a particular time. Decision provenance connects that event to the evidence selected, the intermediate recommendation, the approval state, and the authority under which the change occurred. The organization does not need to preserve every internal computation a supplier cannot expose. It does need enough reliable evidence to explain its own regulated action and investigate a failure.
Segregation of duties also requires attention. If one agent retrieves the evidence, selects what is relevant, interprets it, drafts the conclusion, and evaluates its own result, several responsibilities that were separate in the human process may have collapsed into one technical pathway. A second agent is not independent merely because it has a different label. Independence depends on the data, methods, failure modes, and authority used for the check.
A complete audit trail can record a bad decision perfectly. The organization needs both a sound decision and reliable evidence of how it was made. Retention should follow the task, applicable predicate rules, risk, investigation needs, privacy, confidentiality, and contractual obligations. Indiscriminate logging can create uncontrolled copies without improving assurance. Exact reproducibility may be impossible for a probabilistic service, but the organization should still preserve enough historical evidence to explain the regulated decision. If exact reproduction is required, that requirement should shape the system choice before approval.
Stage 3: Test the complete workflow
Stage 3 determines whether the configured system and assigned people can perform representative work under realistic conditions, first well enough for a bounded pilot and then well enough to support a separate routine-use decision.
Test the evidence and the review conditions
A citation is a starting point for verification. The source must exist, support the statement, and apply to the case. A true statement about another product, site, jurisdiction, process stage, or document revision can produce a wrong conclusion in the present workflow.
A summary can accurately describe five retrieved deviations and still omit a sixth that changes the conclusion. Citations to the five will not reveal the missing record. The team needs a justified method for identifying which records belong in the review and detecting consequential exclusions. Agreement is not an independent check when both reviewers depend on the same incomplete evidence path.
Make clear whether an output reports a fact, presents a calculation, offers an explanation, or proposes an action. Compare a factual statement with its source, repeat a calculation, and test an explanation against alternatives and contradictory evidence. Preserve the distinction between chronology and causation. If an excursion follows an intervention, the sequence may justify investigating a connection; it does not establish that the intervention caused the excursion.
The phrase "human in the loop" identifies a person's position, not the effectiveness of the review. Review depends on competence, evidence access, available time, interface design, and practical authority to reject or escalate. Showing a persuasive AI conclusion before the evidence may bias the reviewer's search. For consequential recommendations, the workflow can require an initial evidence assessment before displaying the AI conclusion, or another method that reduces anchoring. Lower-risk transformations may need only a direct source comparison.
Workload is part of the control. Increasing output while reducing the time available for each review can weaken the approval on which the process depends. A reviewer who may reject an output but is penalized for delay receives conflicting instructions. The evaluation and later monitoring must examine review time, queue size, escalation patterns, and whether staff can report uncertainty and near misses without pressure to approve.
Treat automation bias as a control failure mode
For this method, automation bias is a foreseeable control failure mode when an AI-supported workflow shifts a reviewer from active analysis to passive monitoring. The risk increases when outputs are fluent, highly structured, usually correct, presented at high volume, or easier to accept than to challenge. Stage 3 must therefore test whether the review design can detect seeded and naturally occurring errors under realistic workload conditions rather than assume that the presence of a qualified reviewer provides detection. [32–38]
Forced verification steps. For consequential outputs, require the reviewer to examine the underlying evidence and record an independent finding before accepting or rejecting the AI recommendation. Identify the critical fields, claims, calculations, and source boundaries that must be checked. Make correction and escalation no more burdensome than acceptance, and test the control with seeded errors whose detection rate can be measured. A signature or checkbox without a recorded basis is not evidence that meaningful verification occurred.
Certainty label presentation. Treat objective verifiability and psychological risk as separate dimensions. A confidence score, traffic-light indicator, or high-certainty label must not conceal data gaps, assumptions, contradictory evidence, or the limits of the calculation. Compare matched review cases in which the indicator appears before and after the reviewer’s initial evidence assessment. If early presentation reduces scrutiny, delay or withhold the indicator until the independent assessment is recorded. Certainty labels may prioritize review effort, but they must not eliminate periodic challenge testing.
Reviewer workload and rotation. Define review-volume, review-time, queue-size, and task-homogeneity thresholds before routine use. When a threshold is exceeded, rotate reviewers, narrow the queue, increase targeted sampling, add an independent examination for high-criticality cases, or pause the workflow. Monitor detection rates, unsupported acceptances, unnecessary overrides, review time, escalation patterns, and near misses by reviewer and period. Declining visible error rates should trigger analysis of both system improvement and possible loss of detectability.
The evaluation must preserve evidence identity. Record the test collection, document versions, inclusion rules, expected findings, tool configuration, reviewer instructions, scoring rubric, and any changes made after results were examined. Reusing the same visible cases for repeated tuning can turn a test into practice. Fresh cases or a protected holdout set are needed when the result will support authorization.
How a critical omission is decided
The acceptance criterion inherits the reliability of the classification behind it. Zero critical omissions across 59 cases supports a 4.95% upper bound only if a critical omission means the same thing to every person who scores a case. A confidence bound computed over an unstable classification is arithmetic, not evidence.
Before holdout evaluation begins, the protocol must define the case set and drawing method, critical-omission definition, scoring rubric with worked positive and negative examples from the same record population, evidence hierarchy for conflicting records, and disagreement process. Two qualified adjudicators score each candidate critical omission independently, blinded to the AI-supported or baseline condition and to each other’s decision. Neither may have built, configured, tuned, or selected evidence for the workflow, or be accountable for the pilot’s outcome.
Establish classification reliability on a separate calibration collection drawn from the same record population and enriched with seeded critical omissions. The calibration collection is excluded from the holdout. Before calibration, freeze the definition, rubric, evidence hierarchy, reviewer qualifications, disagreement process, and reliability acceptance criteria. Record raw agreement and positive specific agreement. If a chance-corrected measure is also used, interpret it alongside those measures rather than as a standalone pass or fail criterion in a sparse-event classification.
Retain both initial independent decisions, each rationale, and the documented resolution. A qualified tiebreaker who did not author the rubric and is independent of the workflow owner resolves disagreements. While unresolved, a split counts as a critical omission. If the calibration criterion is not met, revise and recalibrate outside the protected holdout. A material change after scoring requires full rescoring under the new rule, with the change and rationale recorded; otherwise withdraw or narrow the evidence claim. Only then may the frozen method be applied to the untouched holdout supporting authorization.
The binomial bound applies only after the critical-omission classification method itself is shown to be stable enough for the authorized use. High agreement shows consistent application, not that the rule is correct. The worked examples and quality-unit review establish whether the rule itself is adequate.
The comparison must count more than average accuracy. Track these metrics separately:
- Critical misses. Consequential failures that easier successes cannot offset.
- False connections. Unsupported relationships that could misdirect an investigation.
- Correct findings rejected. Sound findings rejected without an evidence-based reason.
- Unnecessary escalations. Incorrect referrals that add burden without improving control.
Measure the time required to reach an acceptable evidence packet, not merely the time to generate the first draft. Record withdrawals and incomplete work rather than silently excluding them. If the sample is small, present the uncertainty instead of converting a few cases into a precise-looking percentage.
Before evaluation, define the performance needed for the bounded use and the improvement that would justify the added intervention. A qualification method that raises examination scores without improving independently assessed work has not demonstrated its intended value. If an interface change produces the same benefit with less burden, that alternative deserves consideration. The added controls must earn their place through evidence.
State the required benefit and reviewer-burden limit in the same acceptance criterion. Define the review effort per completed case at which the assigned reviewer can still perform the verification on which authorization depends, and treat a result above that limit under the pre-set monitoring rule as a failed condition rather than an operational inconvenience. A workflow that meets its omission criterion only when reviewers work beyond that limit has not demonstrated acceptable performance. It has demonstrated performance under conditions the organization does not intend to sustain.
The limit belongs in the acceptance criterion because workload is part of the control. An approval produced under a queue that prevents examination is not evidence of review. Set the limit, monitoring window, summary measure, and action threshold before evaluation begins, informed by the measured baseline, the verification required for the authorized use, and defined operating capacity. A limit chosen after results are known describes what happened rather than what was required.
Empirical research supports testing the combined arrangement. Vaccaro and colleagues' meta-analysis covered 106 experiments and 370 effect sizes. Human and AI combinations performed better than humans alone on average, but worse than whichever component performed best alone. The studies largely predate current generative systems, and none were run under GMP. They show why adding a reviewer cannot be assumed to improve an outcome. [22]
Qualify people for the role they actually perform
Awareness that AI can make mistakes is a beginning, not evidence of readiness. The test is whether someone can identify a consequential defect in representative work, explain why it matters, and accept, reject, correct, or escalate the result appropriately.
Challenge cases must include:
- Correct outputs. Confirm that reviewers do not reject acceptable work merely because AI produced it.
- Awkward but sound outputs. Separate presentation quality from evidentiary correctness.
- Fluent dangerous outputs. Test whether polished language conceals a consequential error or unsupported conclusion.
- Incomplete evidence. Determine whether reviewers detect a missing record that could change the decision.
- Wrong-product sources. Test whether apparently relevant evidence from another product is rejected.
- Cases where blanket rejection is wrong. Confirm that reviewers can accept sound work rather than treating universal rejection as safety.
Count both missed defects and unsupported accusations of error. Decide in advance which serious failures cannot be offset by success on easier items. Assessors must agree on what acceptable work looks like and why; unresolved scoring disagreement weakens the permission decision.
Dell'Acqua and colleagues' randomized study of 758 knowledge workers illustrates the importance of task boundaries. AI improved speed and completion within the tested capability range. On a deliberately selected task outside that range, the AI groups' correctness was about 19 percentage points lower than the control group's. The study concerns consulting work with GPT-4, not pharmaceutical qualification. Its methodological lesson is still useful: evaluation should include conditions where assistance can mislead as well as conditions where it helps. [23]
Qualification must match responsibility. A person using a bounded tool to reformat approved text does not need the same demonstration as a quality approver evaluating an investigation or a system owner granting an agent write access. Training hours and course completion are inputs, not evidence that someone can perform a particular employer's work. This follows the readiness argument I developed for advanced-therapy manufacturing. [24]
A qualification program can also fail by blaming the operator for impossible conditions. If the interface hides source status, the evidence collection is incomplete, or volume makes careful review unrealistic, repeated retraining will not repair the workflow. Training cannot recover evidence the system never makes available.
A passing standard needs a reason. Define which outcomes matter, how cases represent the assigned work, and how assessors will distinguish an acceptable decision from a plausible but unsupported one. Use enough varied cases to avoid granting authorization on the strength of a rehearsed example. Where judgment is involved, calibrate assessors against shared examples and investigate material disagreement. If competent assessors cannot apply the standard consistently, the organization does not yet have a dependable basis for using the result to grant permission.
Qualification must be reassessed when its supporting conditions change. A reviewer qualified on one evidence repository, interface, language, and authority level must not automatically remain qualified after the system begins searching additional repositories or initiating workflows. Requalification can be targeted to the changed function. It need not repeat every prior activity, but the retained evidence must have an explicit rationale.
Challenge agents before routine use
An agent can turn one mistaken interpretation into changes across several systems. Problems can also arise when each tool works but the sequence fails. Consider an agent authorized to open a follow-up task and update a linked record. The first operation succeeds, the second times out, and the agent retries the entire sequence. It creates a duplicate task. The request and generated text were appropriate; the agent lost track of what had already happened.
The system must recognize repeated requests, check the state of prior operations, and expose incomplete work. Verify the actual records rather than treating the agent's completion message as proof. The test protocol must include:
- Duplicate requests.
- Expired approvals.
- Unavailable sources.
- Changed records.
- Interrupted execution.
- Concurrent edits.
- Partial success.
Recovery must distinguish reversible and irreversible actions. A record change may be reversed; an external notification cannot be unsent. Restoring one database may leave another system inconsistent. The recovery plan must specify reconciliation, compensating action, communication, and the authority to suspend the workflow.
Operating hours also matter. If an agent can take consequential action outside staffed periods, the organization needs a response arrangement for those periods. Otherwise, operation may need to be limited to times when responsible people can intervene. Training users to watch carefully cannot replace least privilege, state checks, observable execution, and tested recovery.
Stage 4: Authorize routine use and monitor
Stage 4 applies the gate distinction stated above. The process and quality owners must review pilot performance, critical failures, unresolved risks, review burden, recovery results, and operating controls before granting routine authorization. Any expansion requires another explicit decision.
Continued use requires determining whether the authorized conditions still apply. Model updates, retrieval changes, revised procedures, new products, staffing changes, and added permissions can alter performance or risk. McKinsey's learning-loop model in biopharma R&D offers a useful parallel: later evidence can inform earlier decisions while authority for protocol and regulatory changes remains human. It is a strategic model, not a GMP control standard. [25]
Monitoring must focus on consequential performance. Average quality can remain stable while a rare defect family worsens. Examine relevant products, sites, roles, document types, languages, and failure classes where the data support those distinctions. Keep small samples and uncertainty visible.
Overrides and near misses can provide useful signals, but their meaning requires context. A sudden absence of overrides may reflect improvement, rubber-stamping, poor capture, or migration to an unapproved tool. Stage 0 inventory and ordinary user feedback help identify shadow use that formal metrics miss.
Connect workflow authorization to organizational management review
Every Gate Decision Record must contribute a defined set of fields to an organization-wide AI Authorization Register: the workflow and owners, current decision and authority level, acceptance criteria, reviewer-burden performance limit and current burden against it, review date, open risks, material changes, incidents and near misses, reviewer-performance signals, corrective-action status, and evidence location. The register is an index and aggregation layer, not a substitute for the controlled Gate Decision Record, validation evidence, deviation, change-control record, or CAPA. Aggregation must preserve distinctions by workflow, product, site, role, failure class, supplier, and authority level when a combined average could conceal a consequential problem. [8, 17–18]
Carrying the performance limit into the register lets periodic review ask whether a workflow still earns the review effort it consumes. Quality performance alone cannot answer that question.
A function sufficiently independent of the workflow's operation must periodically test whether authorization and monitoring controls work in practice. The review must use a justified, risk-based sample; trace register entries to source evidence; reconstruct why authorization was granted; compare authorized scope with actual use; examine rejected, withdrawn, and incomplete outputs; determine whether stop triggers were followed; and test whether corrective actions worked on fresh evidence. Independence depends on authority, incentives, access to evidence, and freedom from responsibility for the result, not on the reviewer's organizational label alone. The review may conclude that a control is effective, effective with conditions, partially effective, ineffective, or unable to be determined from the available evidence. [8, 17–18]
Material findings must enter the pharmaceutical quality system's management-review process with the affected workflows, evidence limits, required decision, responsible owner, due date, and method for checking effectiveness. Management action may change resources, policy, supplier controls, common technical controls, risk criteria, or the permitted class of use. Each decision must flow back to the affected workflow through the appropriate change control, CAPA, requalification, restriction, suspension, or retirement record. Management review does not replace quality-unit responsibilities or retroactively make an unsupported workflow acceptable. [8, 17–18]
Stage 5: Change, correct, reauthorize, and retire
Assess what a change could affect before selecting the tests. A wording edit that leaves behavior unchanged may need little additional assurance. A change in source selection may require targeted regression cases. Granting write access creates a different authority envelope and a different qualified state. The organization must document which prior evidence still applies and which conditions require new testing or requalification. FDA's January 2025 draft similarly describes evaluating relevant AI-model and manufacturing changes through the manufacturer's change-management system within its pharmaceutical quality system. [39]
Approved changes must also reach the right people and systems. A revised procedure may affect particular sites, roles, work instructions, assessments, and permissions. Assigning the document to everyone is easy to count but does not show that the correct intervention occurred. Some changes require awareness; others require practice, observed demonstration, requalification, or a change in authorization. A governed applicability process must identify affected relationships from approved sources, show the basis for each proposed connection, and leave uncertain cases for responsible review. [26]
When a failure occurs, determine its scope, preserve the evidence, restrict affected use when warranted, and investigate human and system causes. Retraining is appropriate when a person lacked a required skill. It will not repair missing evidence, an interface that hides limitations, a defective permission design, or unreliable equipment. Corrective action must face fresh cases that reproduce the failure mechanism, along with unaffected cases that check for new errors.
Correctability means being able to find a problem, determine what caused it and what it affected, correct it under change control, and test whether the correction worked. Completing retraining or changing a prompt establishes that an action occurred, not that it worked. The final decision may be to reinstate the workflow, narrow it, stop it, or retire it. Retirement should address remaining records, access, supplier dependencies, and continuity obligations.
Count the time and cost of the whole job
AI saves little if people cannot check its work well enough to use it. Measure the time and effort required to finish an acceptable piece of work, including review, correction, escalation, maintenance, and downstream rework. Drafting speed alone does not show that the process improved. [27]
Sanofi reports reductions of up to 80% in time and effort for generative-AI-assisted manufacturing reports, beginning with annual Product Quality Reports (PQR) and extending to other manufacturing documentation. The public account does not provide enough detail to calculate the cost of an approved report or the burden of all controls. It nevertheless provides a relevant operating example of realized drafting benefit. [28]
A published case study of AstraZeneca's AI-governance implementation describes approximately four full-time staff coordinating the effort during 2020 and 2021 and a 14-week audit requiring about 2,000 person-hours, without technical testing of individual models. These estimates belong to that program and do not measure reduced AI error. They show why governance labor must be included in the business case. [29]
Evidence outside pharma also shows why benefits should be measured by task and user. Brynjolfsson, Li, and Raymond's published study of 5,172 customer-support agents found a 15% average increase in issues resolved per hour, with larger gains among less-experienced workers. It was a staggered deployment in one firm, not a GMP trial. It cautions against assuming that the most experienced workers always benefit most or that AI necessarily prevents learning. [30]
Before a pilot starts, define what should improve and what cannot worsen. An SOP gap-check tool might be expected to reduce search time without increasing consequential omissions or false alarms. Measure the current process first. Compare time to acceptable work, important errors, unnecessary escalations, review burden, and maintenance cost over an agreed period.
These measurements are gate evidence, not background analysis. The measured baseline belongs to the Stage 1 record. The reviewer-burden performance limit belongs to the Stage 3 acceptance criterion. Current burden against that limit belongs to the Stage 4 monitoring set and the AI Authorization Register. Counted anywhere else, the figures describe the program without constraining it, and a method that cannot constrain itself on burden cannot claim to have tested whether its controls are worth their cost.
Supplier agreements should identify the intended use, evidence each party will provide, acceptance criteria, change-notification duties, records available for investigation, and responsibility for evaluating changes. Delivery of software is not acceptance of the configured workflow. NIST's voluntary Generative AI Profile supports explicit supplier expectations for quality, security, provenance, third-party evaluation, and incident responsibilities, but it does not impose a pharmaceutical contracting rule. [31]
Pharmaceutical companies now have enough operating experience to identify recurring failure modes and propose controls. The public evidence base is not yet mature enough to establish the long-term effectiveness and net cost of a complete governance model. This approach is therefore designed as a testable operating method: it helps organizations decide what AI-supported work may proceed while generating evidence about whether the controls improve the work and justify their cost.
Worked example: applying the cycle at a single site
Consider this question: has a particular quality concern appeared elsewhere, and what evidence should a quality team examine before deciding whether wider action is warranted? The permitted output would be a cited evidence packet with unresolved questions. The system would not declare a site compliant, predict an inspection outcome, or approve corrective action. An authorized quality owner would decide the significance of the findings and any response.
Begin with a bounded evaluation collection reconciled against an inventory. Each consequential statement must link to its original passage, document status, site, date, and translation history where applicable. Include superseded responses and relevant records expressed in unfamiliar terminology. Outside a bounded collection, search limits should remain explicit because failure to retrieve a precedent does not establish that none exists.
Suppose the packet omits a decisive earlier finding recorded in unfamiliar terminology. The returned evidence looks consistent, and the reviewer concludes that the concern is isolated. Reconciliation against the test inventory reveals the omission. The evaluation owner preserves the query, retrieved records, configuration, and review decision, then restricts the affected use while the failure is investigated.
The investigation should distinguish at least three possibilities. If the record was never indexed or the search failed to match its terminology, correct ingestion or retrieval. If the interface concealed search limits or unavailable records, redesign the workflow. If the evidence and limitations were accessible but the reviewer misunderstood their significance, targeted preparation may be warranted. More than one cause may contribute.
Test the correction on fresh cases with similar retrieval problems and on unaffected cases that could reveal new errors. Measure consequential omissions, unsupported conclusions, correct packets wrongly rejected, unnecessary escalation, and review burden. Resolving the original case alone would not justify restoring use. The quality owner should decide whether the new evidence supports reinstatement, narrower scope, continued restriction, or retirement.
For structured-data exploration, separate verifiable counts from interpretations. A challenge case can present an apparent rise in findings caused by a changed category definition, duplicate record, or different observation period. The calculation must be reproducible from the underlying dataset with filters and exclusions retained. The reviewer must distinguish a change in recorded data from evidence of worsening performance. When the data cannot support comparison across sites, the system must expose that limitation.
For connections across quality systems, test whether records describe the same issue, related issues, or only similar language. Pair an audit observation with a deviation from a different product and a superficially reassuring response that does not address the original concern. The reviewer must reject the unsupported connection, identify what remains unresolved, and avoid treating a completed response as proof of effectiveness.
Where feasible, compare three conditions: the current search-and-review process, AI assistance with existing preparation, and AI assistance after task-specific preparation. Keep the tool, settings, and source collection the same in the two AI groups so better software is not mistaken for better training. Use unfamiliar cases, distribute difficult cases fairly, and score the work without revealing the condition. Report baseline performance and uncertainty alongside any improvement.
How we would know the approach is not helping
The evaluation must permit the conclusion that an added check, workflow step, or training requirement does not help. A simpler interface, deterministic tool, narrower AI task, or existing process may achieve better results. An assessment that mainly produces documentation or teaches people to pass its own cases has not demonstrated workplace value.
The method is not helping if qualified reviewers cannot reproduce its decisions, if important omissions or false accusations do not improve, if the burden exceeds the task's benefit, if users move to unapproved tools, or if monitoring cannot detect deterioration soon enough to act. Those findings must lead to redesign, restriction, or withdrawal rather than another layer of paperwork.
Decide whether the work can proceed
Before allowing AI to support a consequential quality decision, name the task and accountable owner, examine representative results, and agree on what finding would make the team stop or restrict use. Set a date or trigger for reviewing the evidence again.
What evidence would justify authorizing this workflow? What finding would make us restrict or stop it? Answer both before the work proceeds.